Knowledge base
Everything it knows comes from what you gave it.
Genie AI builds its knowledge from your website and your documents, and shows you exactly which pages it read.
- Sitemap or link discovery, decided by what your site actually publishes
- Scanned, image-only PDFs transcribed page by page
- A written report of what the scan could not cover, and why
Discovering pages
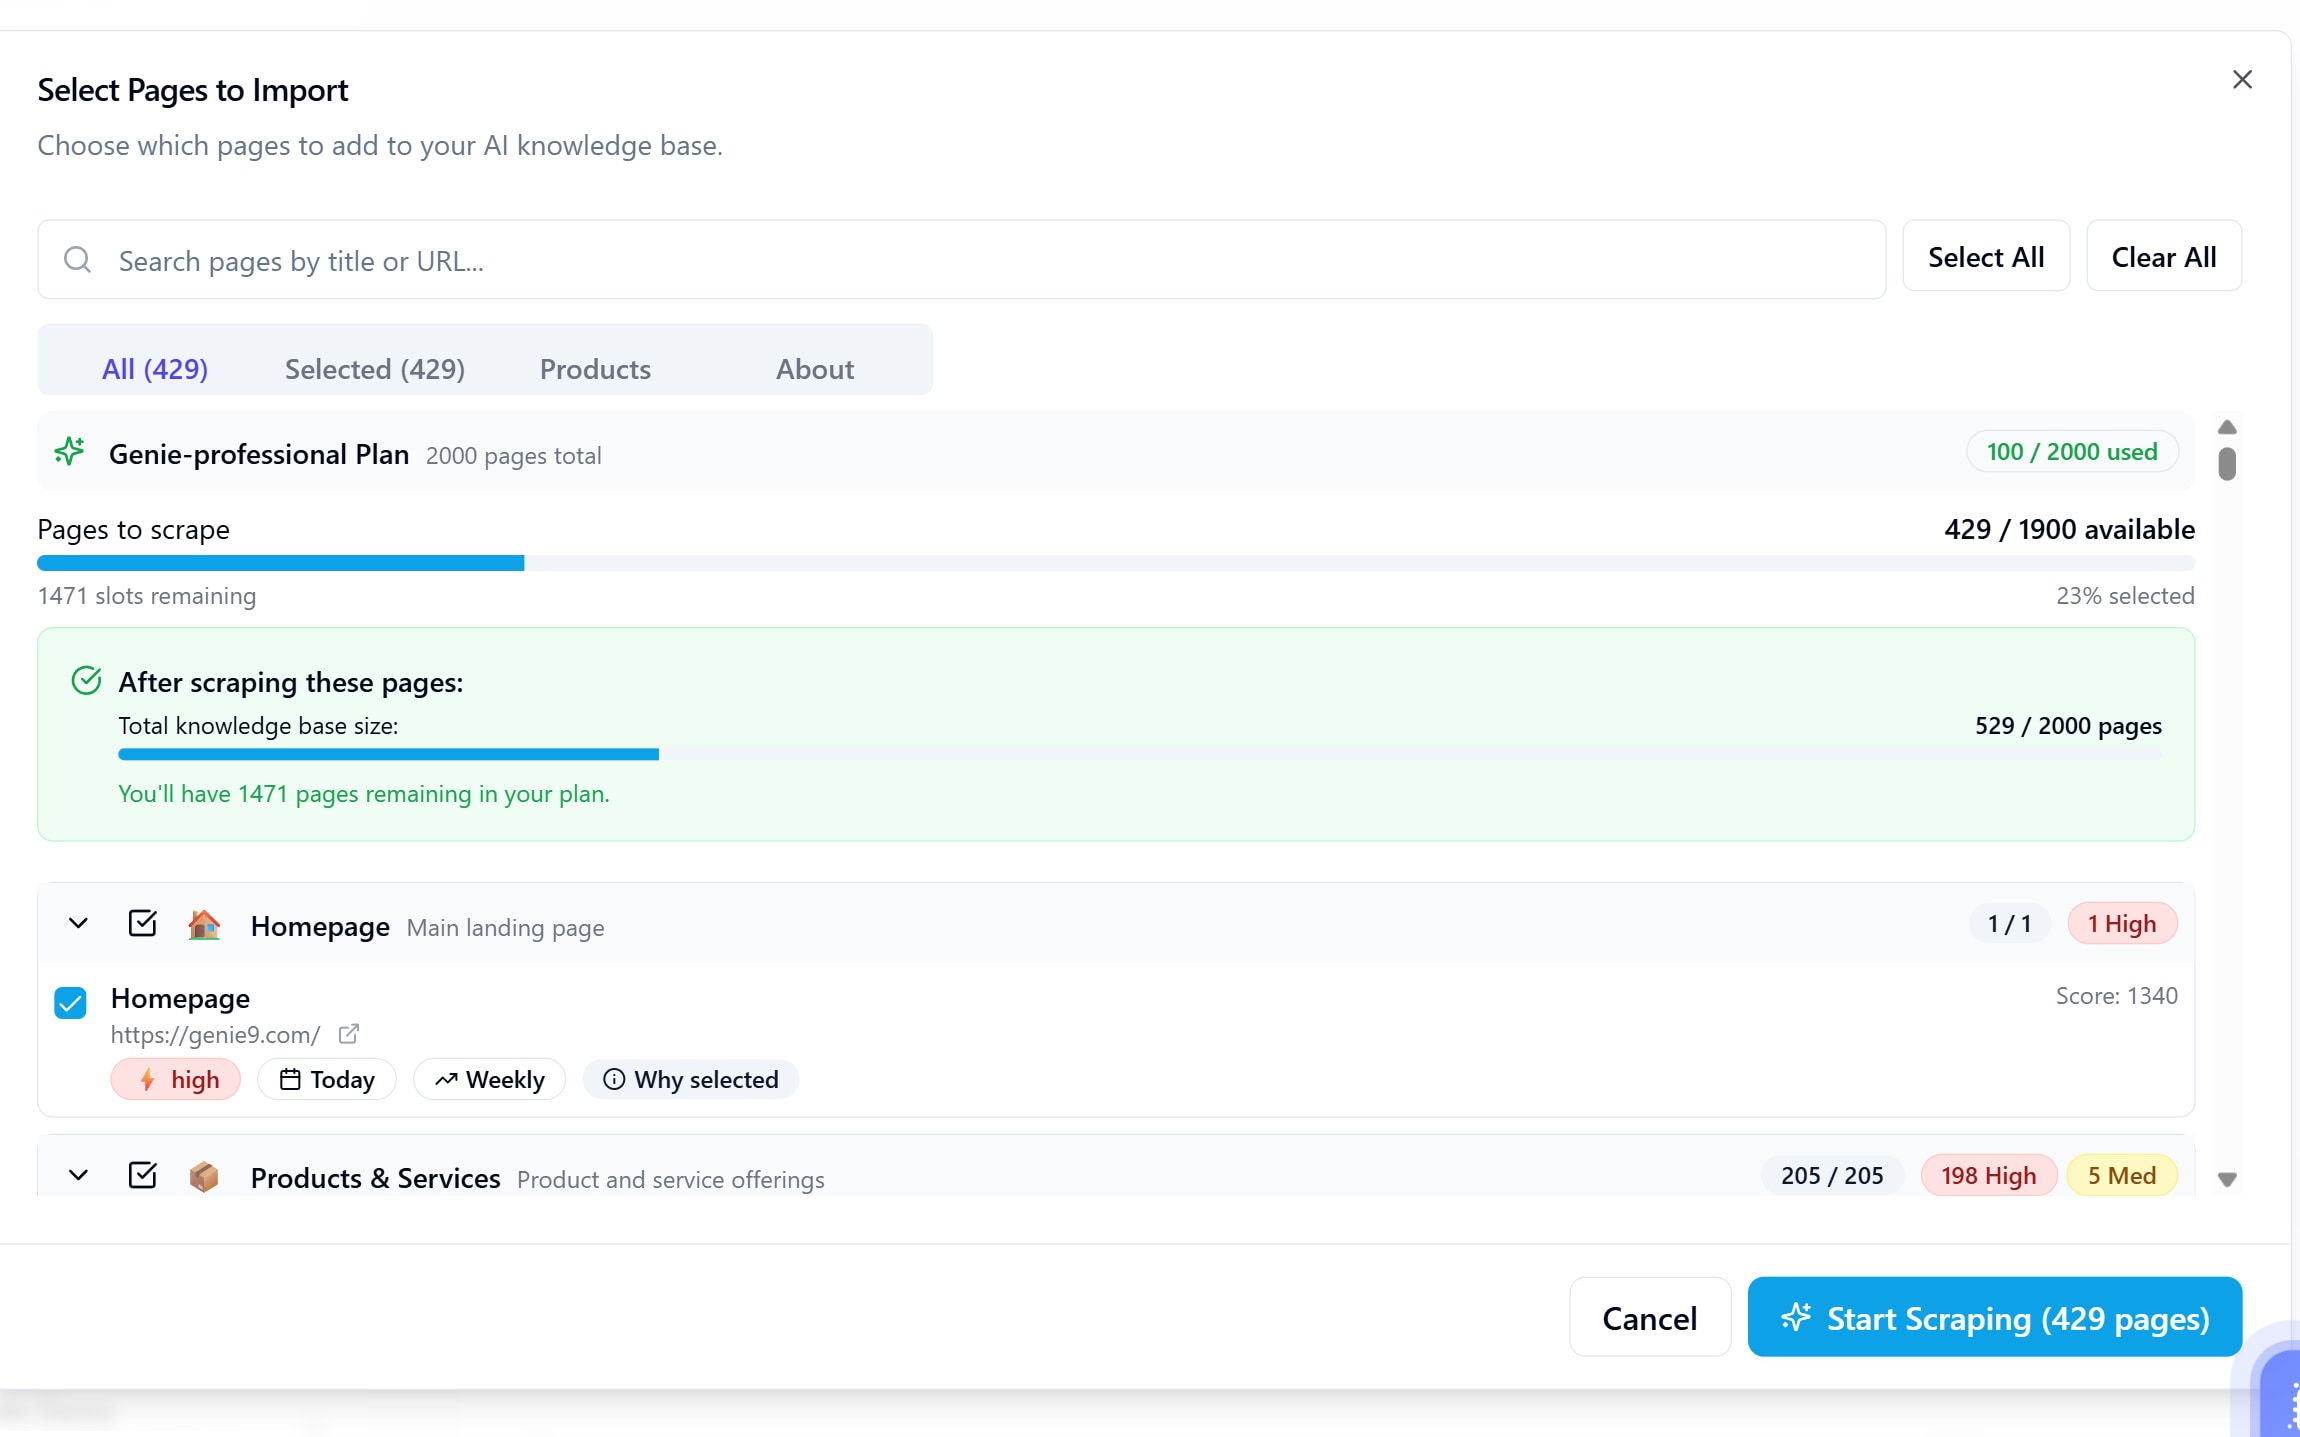
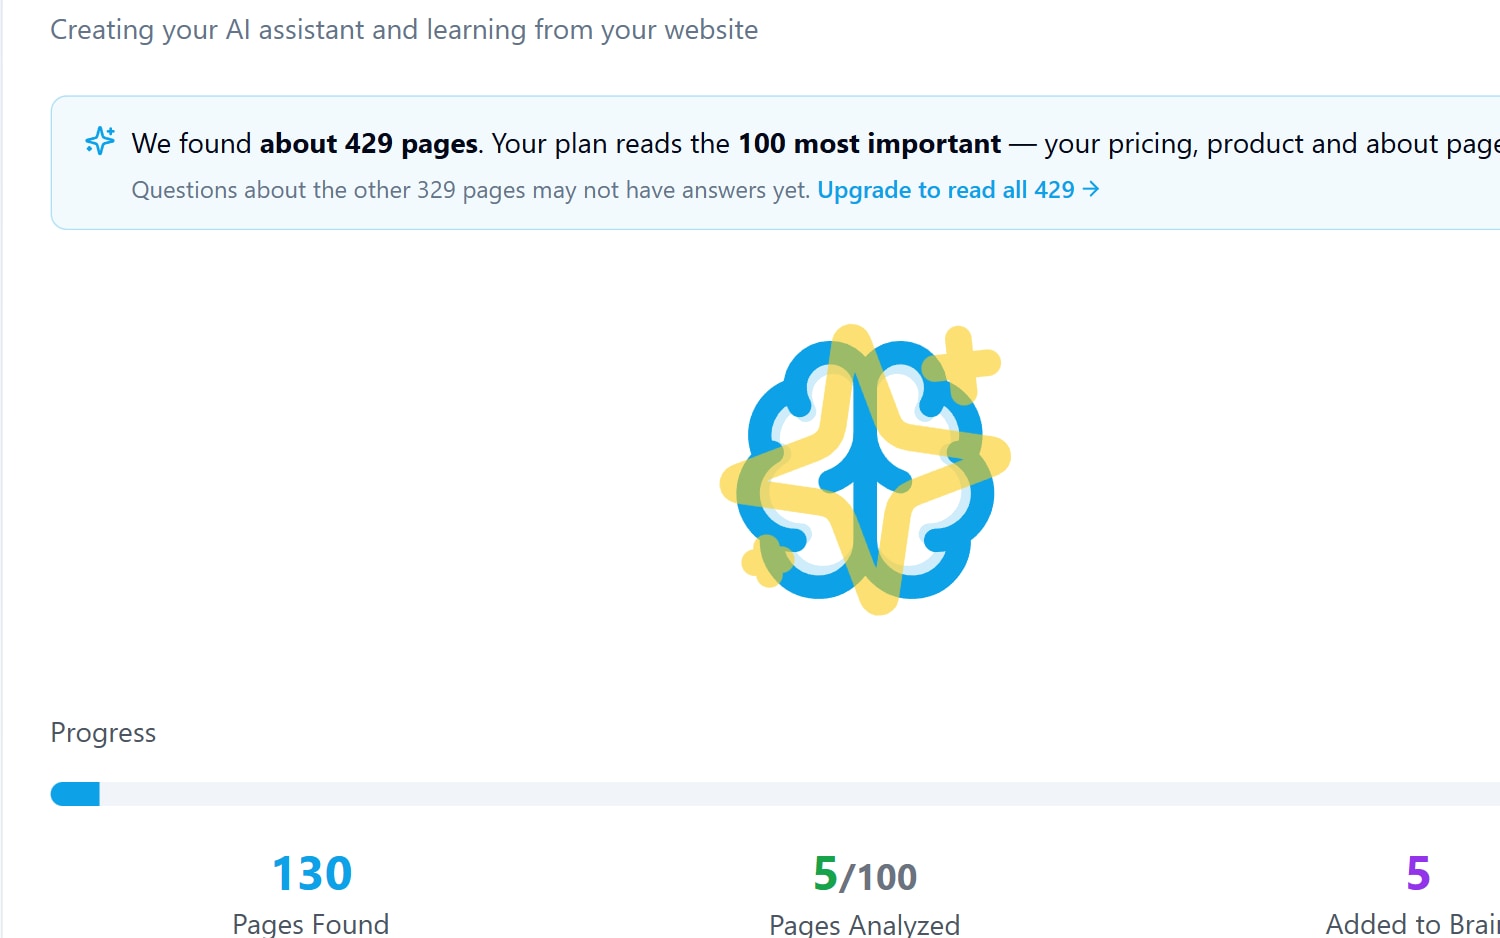
Read your sitemap — found about 429 pages
Checking how to read them
Fetched a sample twice to see which sections need a browser
Reading and indexing
Stripping navigation, rewriting tables, collapsing duplicates
Some of your site was not included.
Your site has at least 429 pages and your plan covers 100, so at least 329 were not read.
The assistant can only answer from what it read. A higher plan raises the limit, or you can scan a specific section on its own so the pages that matter most are the ones included.
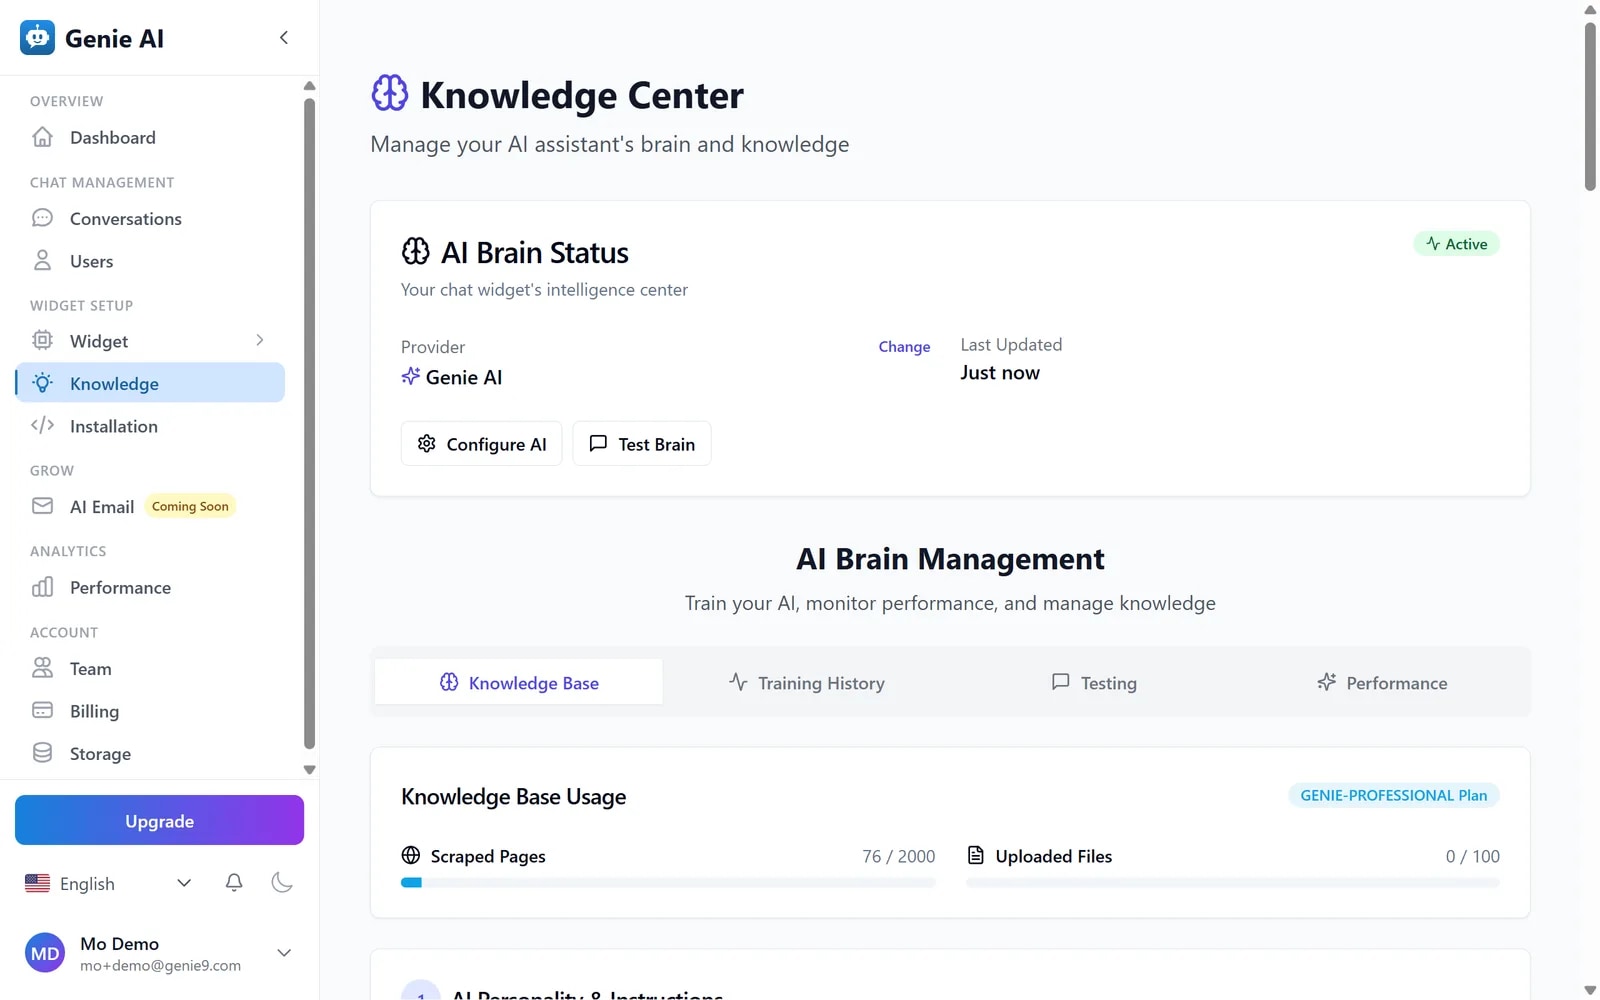
A real scan of genie9.com on the free plan — including what it reported it had missed.
Sitemap first; links when there is none.
With a sitemap, the scan reads the sitemap and follows no links. Without one, it starts at the URL you gave it and follows links on an exactly-matching hostname. Which you get is a fact about your site rather than a setting.
- On a site with a sitemap, a page missing from that sitemap is never discovered — worth checking before you judge the answers.
- Pages are taken round-robin across the sitemaps found, so one enormous section cannot consume the whole allowance.
- Link crawling stays on the exact hostname it started from.
- You can also point it at additional hosts — a docs or help subdomain — up to your plan’s allowance.
 Click to enlarge
What goes in
Three ways content reaches the assistant.
And a narrow fourth: correct an answer the assistant gave, from the conversation where it gave it, and the correction is indexed ahead of your pages. There is still no free-standing FAQ editor and no connector to a third-party knowledge tool.
Your website
Give it your address. It reads your sitemap, or starts at your URL and follows links, staying on the same hostname.
Your documents
PDF, Word, plain text and Markdown, with a per-file size limit set by your plan. Upload a file with the name of one already there and it replaces it rather than doubling it.
Even the scanned ones
An image-only PDF — a handbook somebody photographed years ago — is transcribed page by page by vision so the words inside become answerable. A scanned handbook scored twelve out of twelve on production.
It measures whether your pages need a browser. It does not guess.
Some sites deliver their text in the HTML; others build it with JavaScript after the page loads. So one page from each section is fetched twice — once plainly, once rendered — and the text each produced is compared.
- A unanimous “this section needs rendering” verdict spreads to pages nobody probed.
- A unanimous “it does not” never spreads: wrongly skipping rendering costs you an empty page, wrongly rendering costs a little time.
- A page that fetched perfectly well but yielded no readable text is reported as a failure rather than quietly counted as done.
 Click to enlarge
Getting the text right
Reading a page is not the same as downloading it.
Four things happen between fetching a page and being able to answer from it.
Page furniture stripped
Navigation, footers and lines that repeat across every page are removed, so a menu item does not compete with your actual content at retrieval time.
Comparison tables rewritten
A pricing or spec table is rewritten so each row survives as a sentence — a cell means nothing apart from its column heading.
Near-duplicates collapsed
Pages with the same content are recognised by fingerprint and collapsed, so one page under five URLs counts once.
Old and awkward sites too
Frame and iframe sources are followed like links, so a frameset site whose text lives in child documents is still reachable.
How a scan works
Discover, read, index, report.
Discover
Read your sitemap, or follow links from your URL if there is no sitemap. Two mechanisms, and only one of them runs.
Read
Probe whether a section needs a browser to render, fetch accordingly, then extract the text and strip the furniture.
Index
Split what it read into passages and store them so they can be found by meaning as well as by exact wording.
Report
Tell you what it could not cover — how many pages, which ones failed, why, and what to do about it.
You always know what it read.
When a scan cannot cover your whole site, it says so during setup — how many pages it found, how many your plan covers, and how many it did not read.
- Each limit comes with a reason and a suggested action, not just a number.
- Failures are named individually: a stale sitemap entry, bot protection, a rate limit, a redirect loop, a certificate problem, or a page that loaded with no text worth reading.
- The page count is stated as a floor, so what you see covered is genuinely covered.
 Click to enlarge
Keeping it current
You decide when it learns something new.
Refresh on your schedule
When your site changes, press refresh and the scan runs again. Its answers change when you decide they should, and not before.
Teach it a better answer
Open a conversation where the assistant answered badly, press Improve this answer, and write what it should have said. The correction is stored against that question and ranked above your pages and documents. Owners and admins can do this; a member cannot.
Point it at your site and see what it finds.
The free plan scans your site and tells you exactly what it could and could not read. No card, no expiry.